|
I'm a first-year Ph.D. student at MMLab, The Chinese University of Hong Kong, advised by Prof. Hongsheng Li. My research interests currently center on multimodal pretraining, from architecture design to training dynamics to data analysis. I'm also interested in agentic learning, embodied intelligence, visual generation, and LLM reasoning. I received my bachelor's degree from Xingjian College, Tsinghua University in 2026. During my undergraduate studies, I did research at LeapLab, Tsinghua University, advised by Prof. Gao Huang. If you're interested in my research, feel free to reach out, I'm always open to discussion and potential collaborations. CV / Google Scholar / Github / Twitter WeChat: qihang_peng Email: pengqihang22@gmail.com |
|
|
|
*Equal contribution |
|
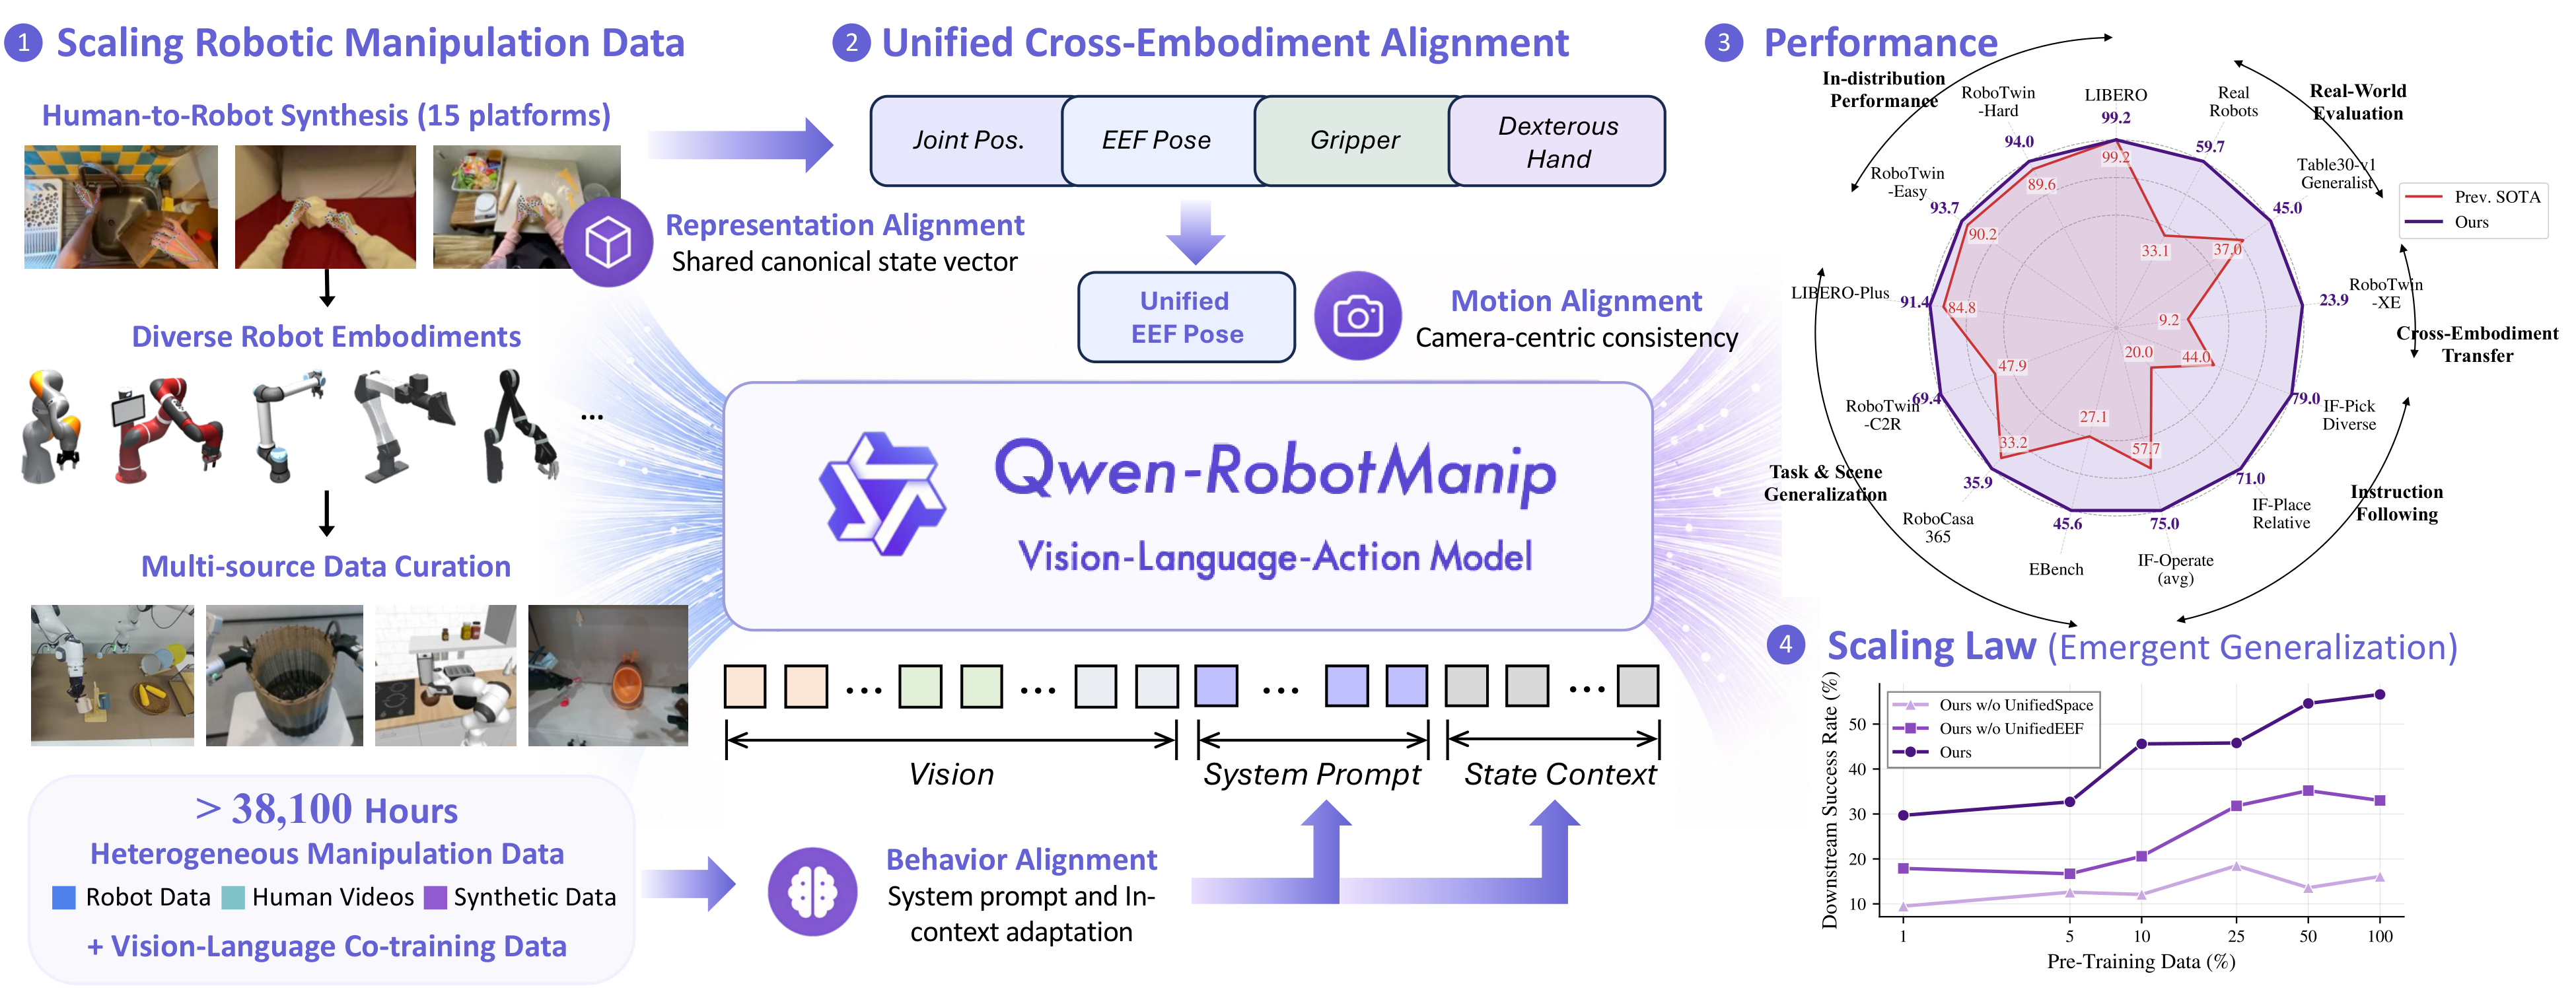
Qwen Team (Qihang Peng as Core Contributor) Tech Report, 2026 [arXiv] [Blog] A generalist robotic manipulation foundation model that aligns representations, motions, and behaviors across 15 robot platforms. Trained on ~38,100 hours of pre-training data. Ranks first on RoboChallenge and surpasses π0.5 across 6 OOD benchmarks. |
|
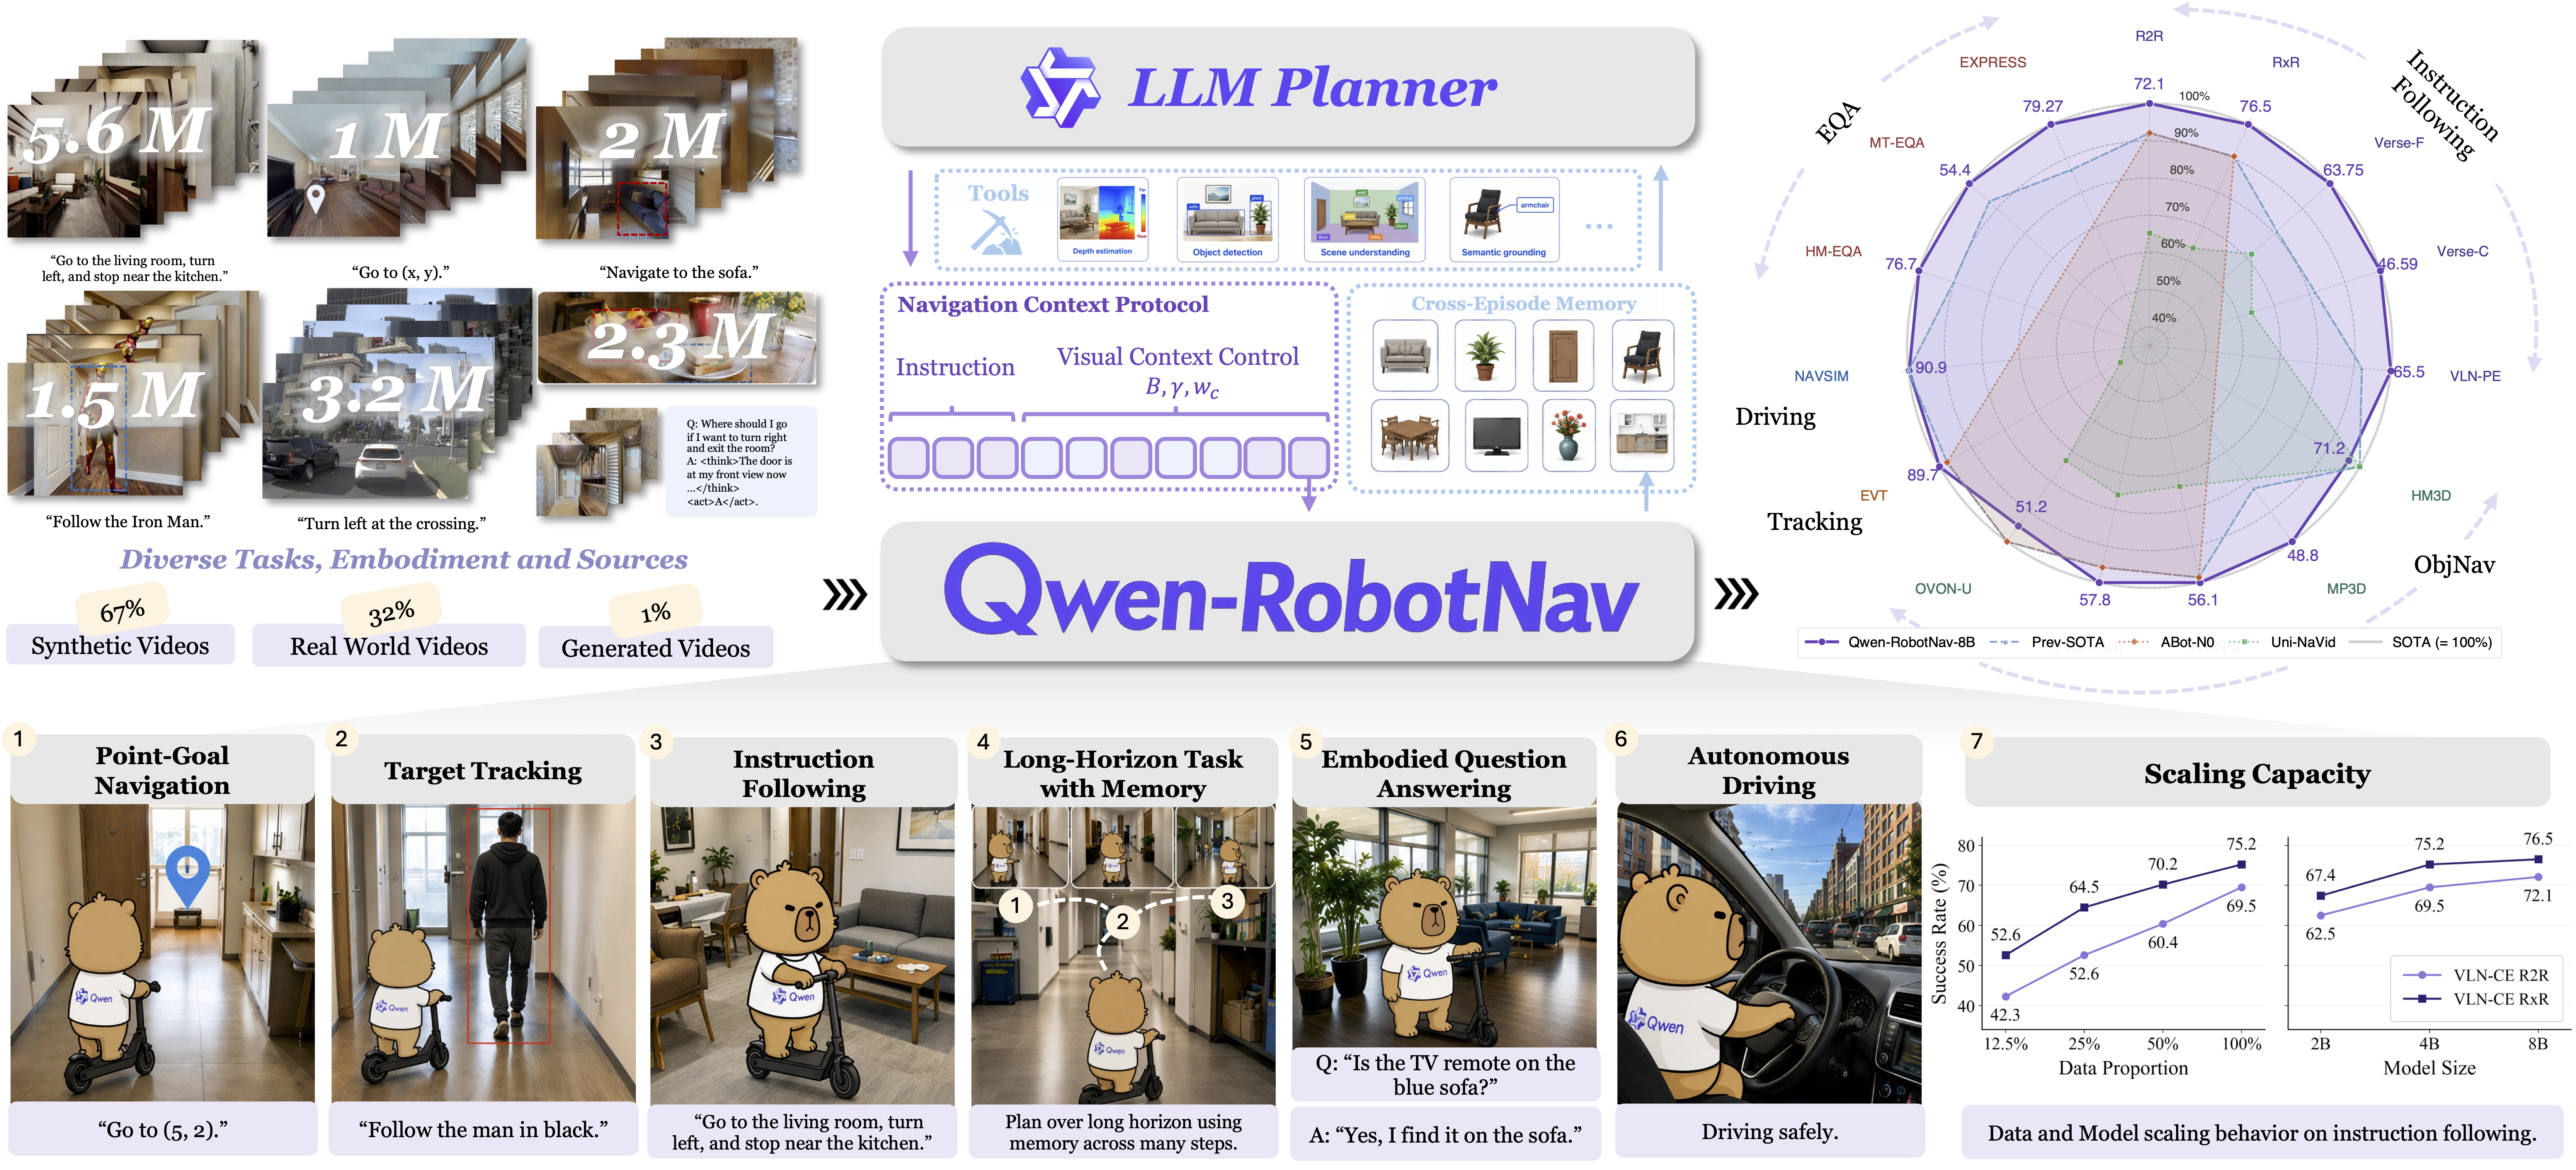
Qwen Team (Qihang Peng as Core Contributor & Co-first Author) Tech Report, 2026 [arXiv] [Blog] A unified navigation model built on Qwen3-VL spanning 5 task families with 15.6M training samples. Achieves SOTA on VLN-CE RxR, HM3Dv2, EVT-Bench, and NAVSIM with real-world deployment on Unitree Go2 quadruped robot. |
|
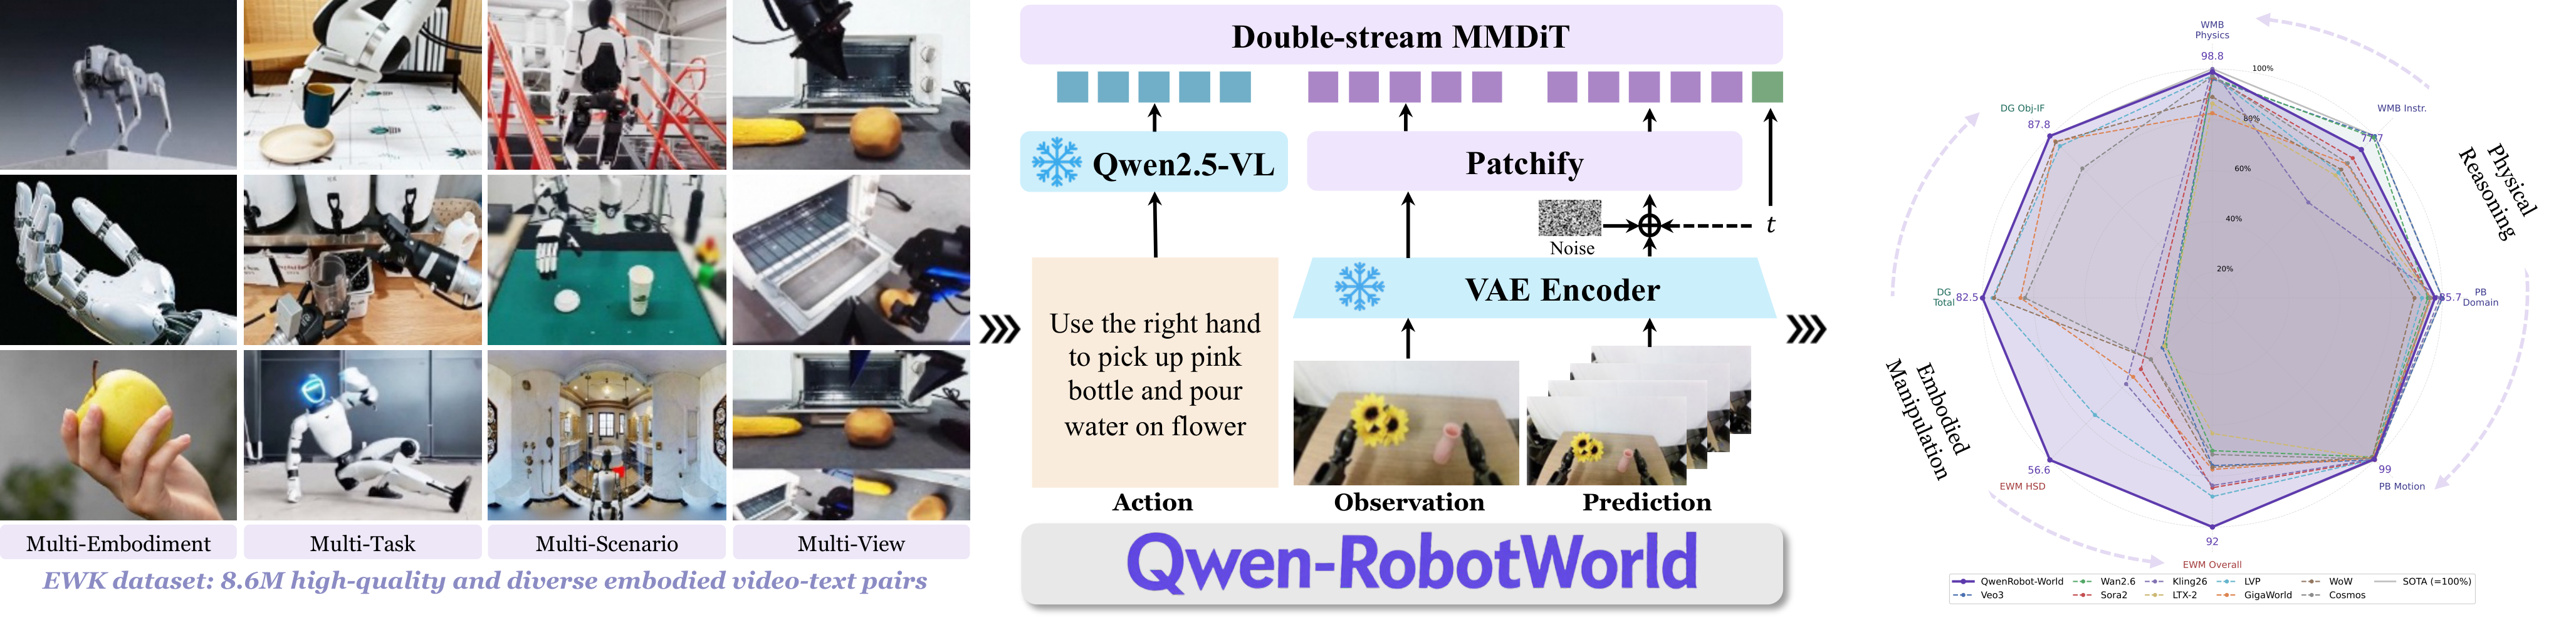
Qwen Team (Qihang Peng as Contributor) Tech Report, 2026 [arXiv] [Blog] A language-conditioned video world model with dual-stream MMDiT and MLLM action encoding, trained on 8.6M video-text pairs across 20+ robot morphologies. Ranks #1 on EWMBench, DreamGen Bench, and leads open-source models on WorldModelBench and PBench. |

|
Qihang Peng, Xuesong Chen, Chenye Yang, Shaoshuai Shi, Hongsheng Li IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2026 [arXiv] [Code] [Project Page] 
ColaVLA moves VLM reasoning into a compact latent space and decodes multi-scale causal trajectories in one pass. State-of-the-art in both open-loop and closed-loop settings with favorable efficiency and robustness on the nuScenes benchmark. |
|
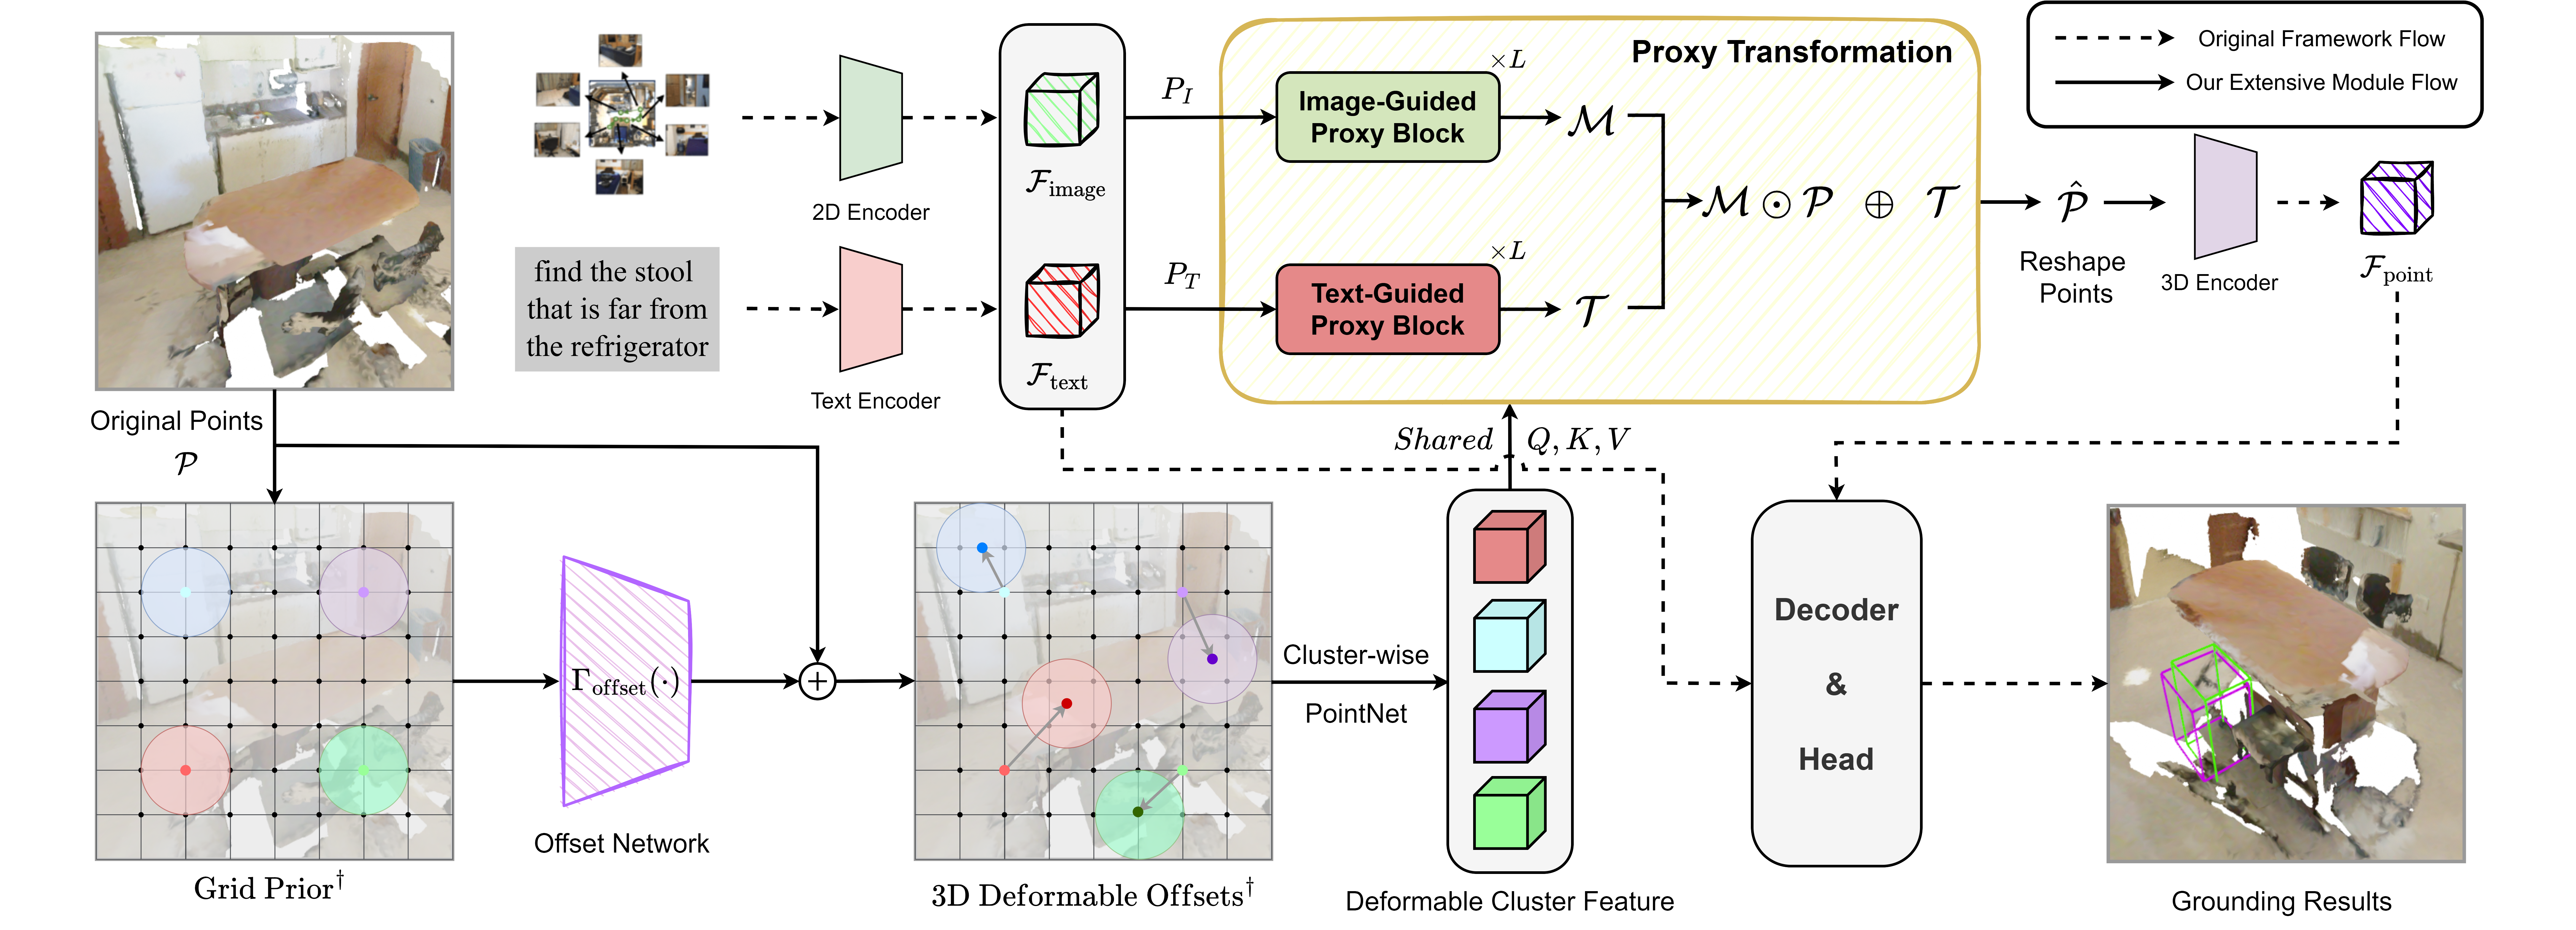
Qihang Peng, Henry Zheng, Gao Huang IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025 [arXiv] [Code] [Project Page] 
Make full use of multimodal information in ego-centric 3D visual grounding for point enhancement. State-of-the-art on the EmbodiedScan benchmark. |
|
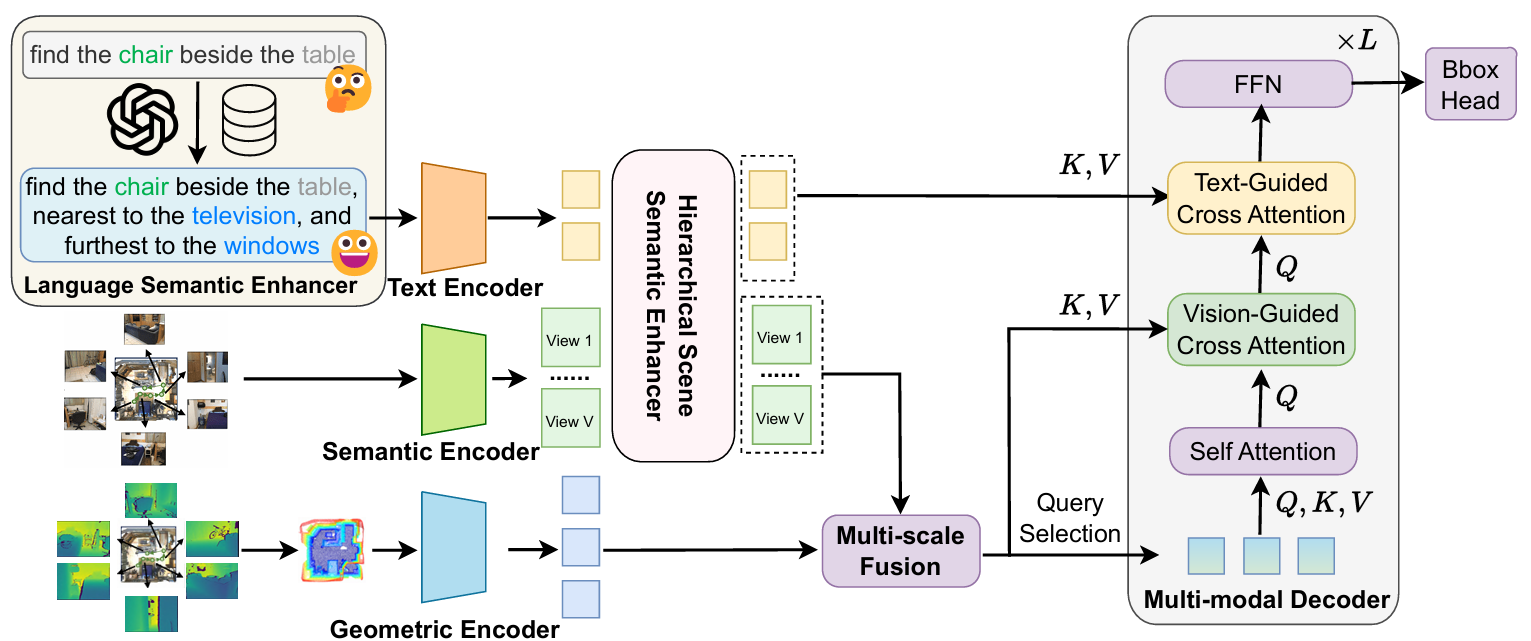
Henry Zheng*, Shi Hao*, Qihang Peng, et al. International Conference on Learning Representations (ICLR), 2025 [arXiv] [ICLR 2025] [AGC 2024] Use LLM and Ground Truth to enhance semantic details in prompt to reduce the ambiguity during training. Extract individual view semantics and enrich visual representation with global scene-level semantic. |
|
|
|
The Chinese University of Hong Kong
Ph.D. in Electronic Engineering Aug. 2026 - Present MMLab, advised by Prof. Hongsheng Li |
|
Tsinghua University
B.Eng. in Mechanics & Vehicle Engineering Sep. 2022 - Jun. 2026 Rank 1st in major with National Scholarship |
|
|
|
Qwen Team, Alibaba Group
Research Intern, working on Embodied Intelligence and VL Pretraining. Apr. 2026 - Present Advised by Dr. Xiong-Hui Chen and Shuai Bai |
|
Voyager Research, Didi AutoDriving
Research Intern, working on VLAs for autonomous driving. Jul. 2025 - Mar. 2026 Advised by Dr. Shaoshuai Shi |
|
LeapLab, Tsinghua University
Research Assistant, working on 3D visual grounding. Feb. 2024 - May 2025 Advised by Prof. Gao Huang |
|
|
|
[Midterm Lecture] [Final Lecture] |
|
|
|
|